Introduction
The Field of Speech Processing study about speech signal and the methods to process it.
- Digital Speech Coding
- Speech Recognition
- Speech Synthesis
- Spoken Language Dialog System
Digital Speech Coding is the process of converting speech signals into digital format. Compress and reliably transmit speech in digital systems with quality/bit-rate trade-offs. The motivation is higher capacity (compression), better quality (error control/equalization), security (encryption), lower OAM cost.
Automatic Speech Recognition (ASR)
Speech Recognition is an interdisciplinary subfield of computer science that develops methodologies and technologies to enable the recognition and translation of spoken language into text by computers with the main benefit of searchability.
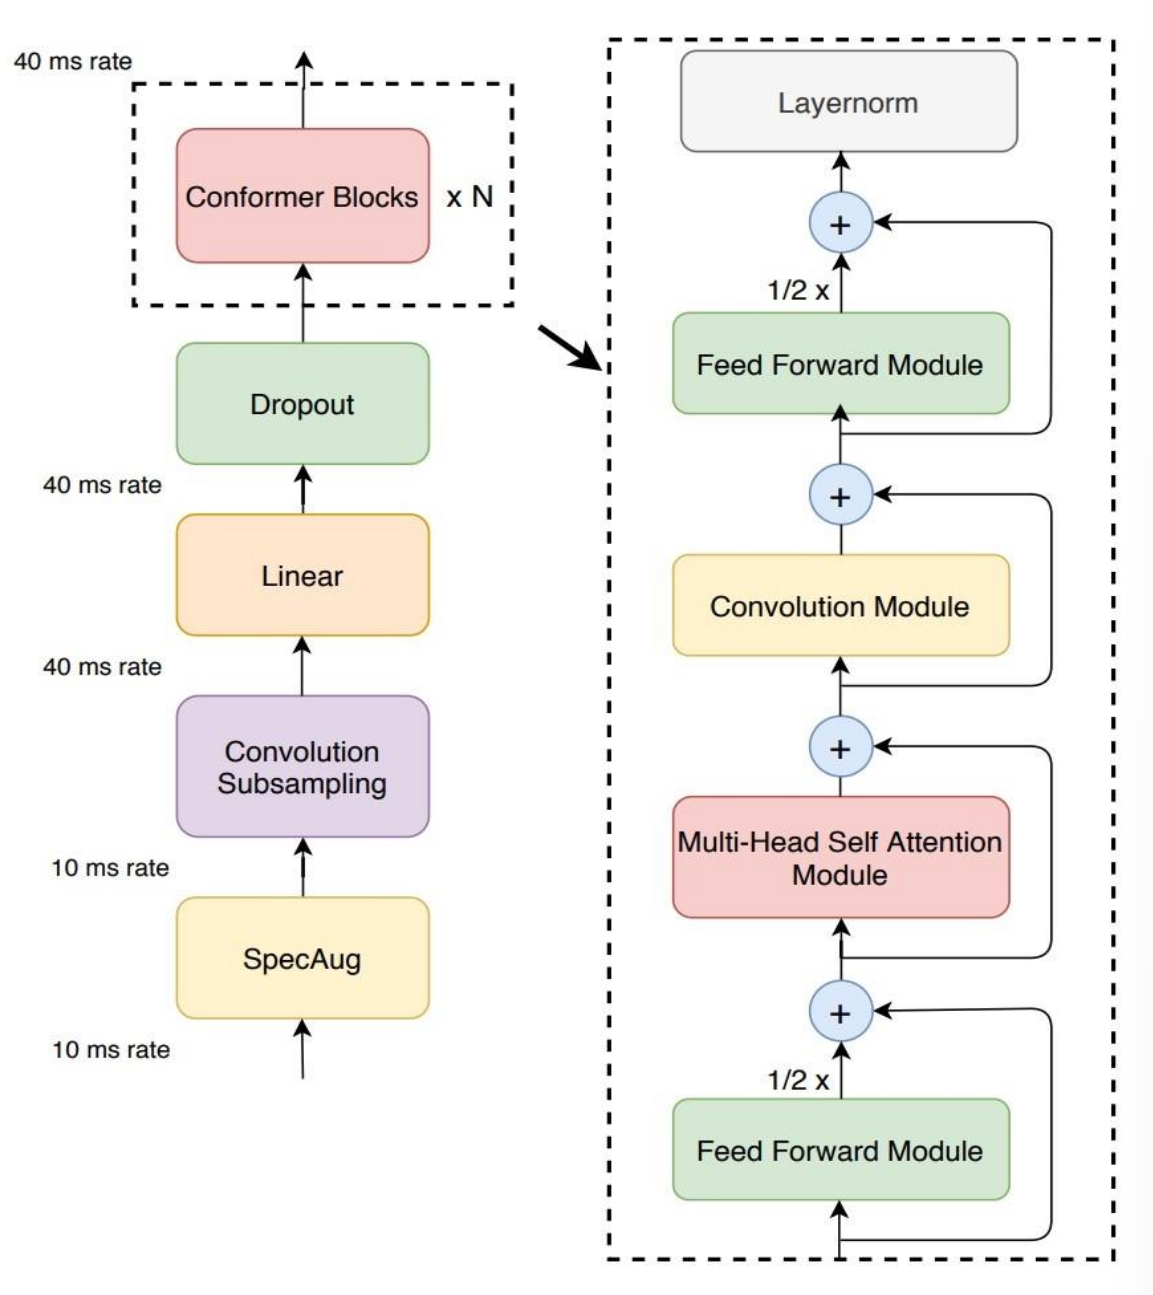
Conformer: Convolutional Transformer Encoder (2020). Seq2seq transformer with multi-headed self attention. Combines attention (global context) and convolution (local invariance).
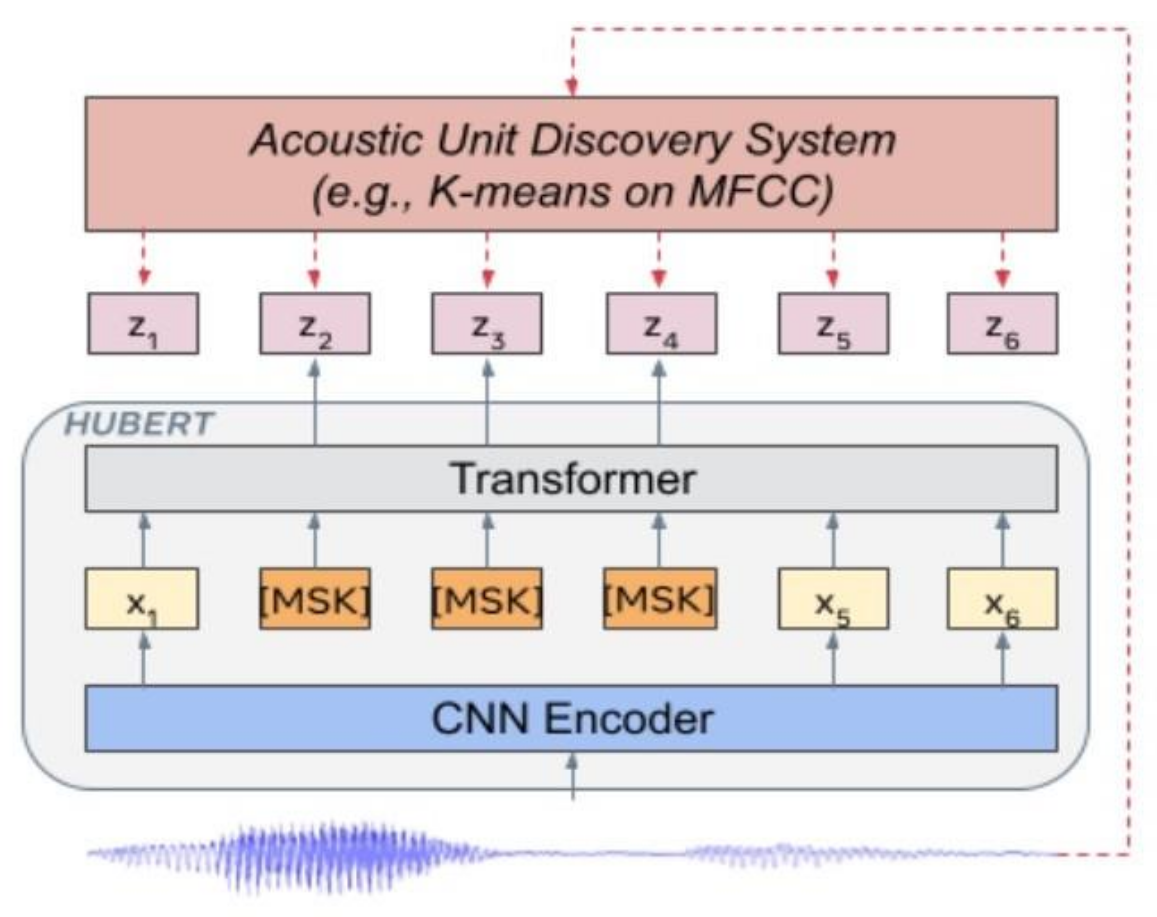
HuBERT: Hidden Unit BERT (2021). Self-supervised learning for ASR. Utilizing K-means clustering procedure to iteratively update cluster / quantization. Mix predicting quantized vectors for masked + unmasked outputs. Useful pre-training for ASR task and better on low resource datasets.
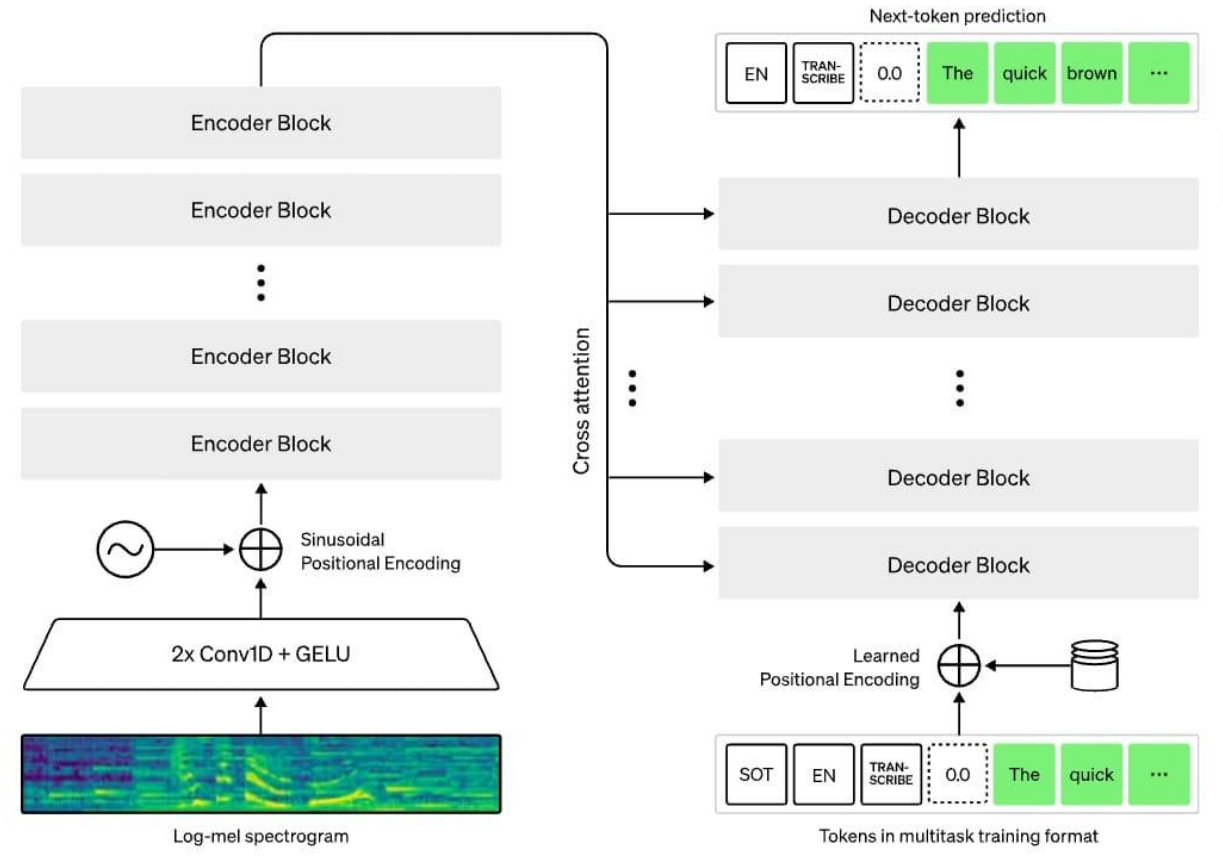
Whisper. Trained on 680,000 hours of multilingual and multitask supervised data collected from the web. It enables transcription in multiple languages, as well as translation from those languages into English.
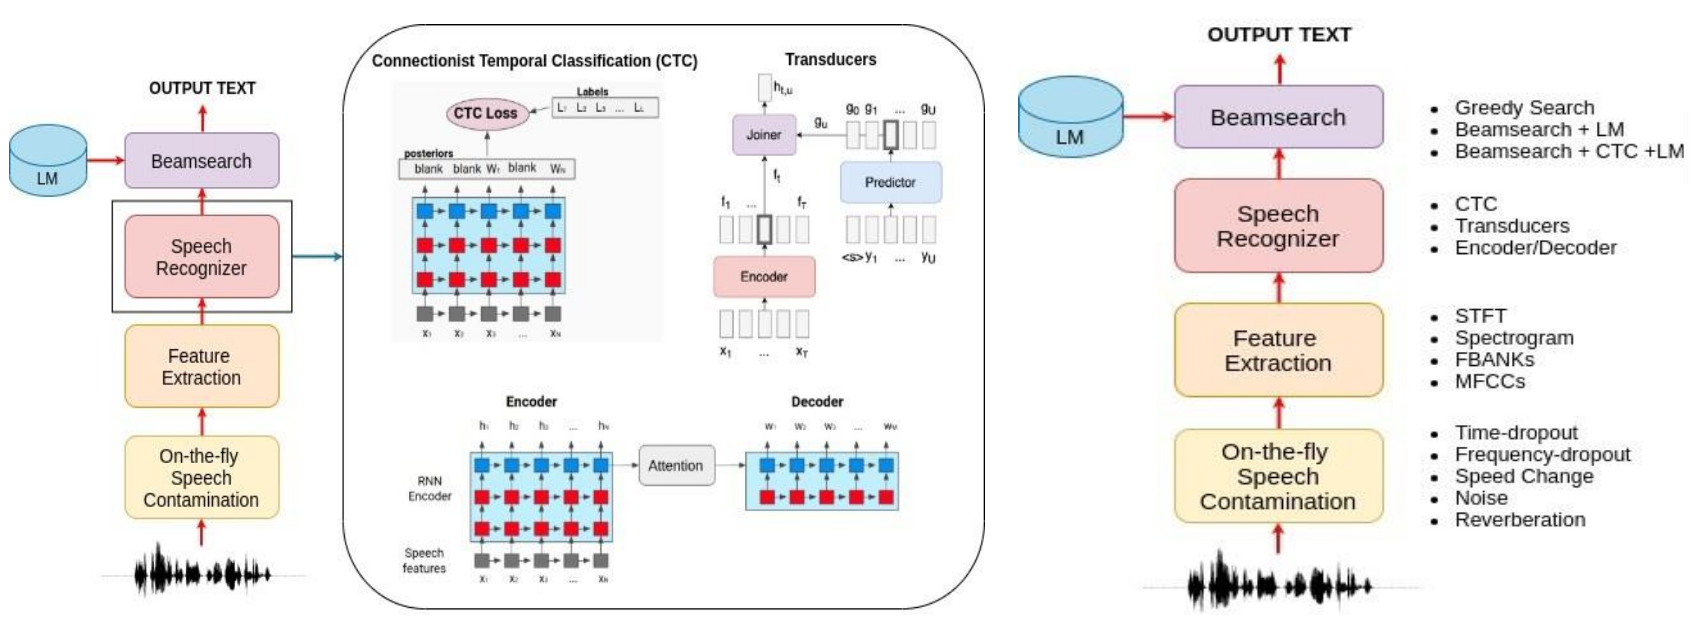
SpeechBrain. Full ASR toolkit integrated with PyTorch.
Extracted Information from Speech.
- Recognition
- Speech
- Emotion
- Age
- Language
- Dialect
- Key Word
- Speaker Recognition
- Speaker Identification
- Speaker Verification
- Speaker Diarization
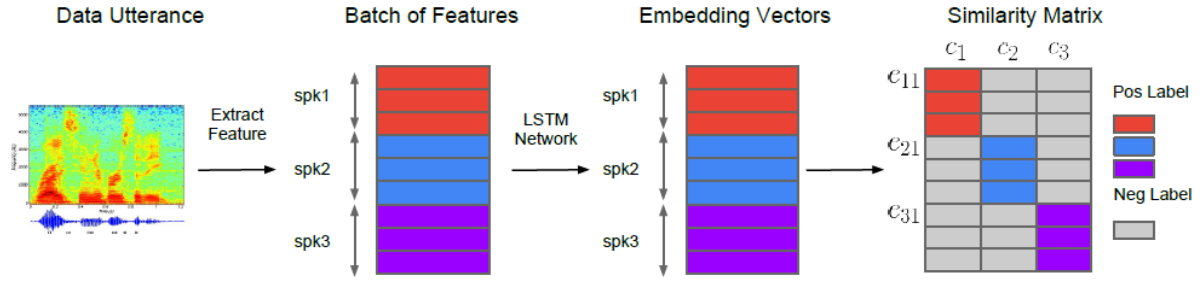
Automatic Speaker Verification: D-vector Speaker Encoder GE2E. D-vector speaker encoder architecture (3 LSTM followed by linear projection) trained isong GE2E loss.
LVCR: Large Vocabulary Continuous Speech Recognition. Dataset with ~64,000 words.
- Speaker independent (vs. speaker-dependent)
- Continuous speech (vs isolated-word)
Is speechrecognition solved? Why study it vs use someAPI? In the last ~12 years
- Dramatic reduction in LVCSR error rates (16% to 3%) in ideal conditions
- New deep learning paradigms for recognizers (end-to-end neural networks and foundation models)
Understanding how ASR works enables better ASR-enabled systems.
- What types of errors are easy to correct?
- How can a downstream system make use of uncertain outputs?
Next generation of ASR challenges as systems go live on phones and in homes.
Speech Recognition Design Intuition
- Build a statistical model of the speech-to-words process
- Collect lots and lots of speech, and transcribe all the words.
- Train the model on the labeled speech
- Paradigm: Supervised Machine Learning + Search
Text-to-Speech (TTS)
Text-to-Speech (TTS) is an NLP system that learns how a computer can read text or symbols and pronounce them by producing soundwaves automatically.
Application Example:
- Personal Assistants
- Apple Siri
- Microsoft Cortana
- Google Assistant
- Games
- Announcements / voice-overs
- Voice cloning. TTS systems that mimic particular speakers with minimal training data
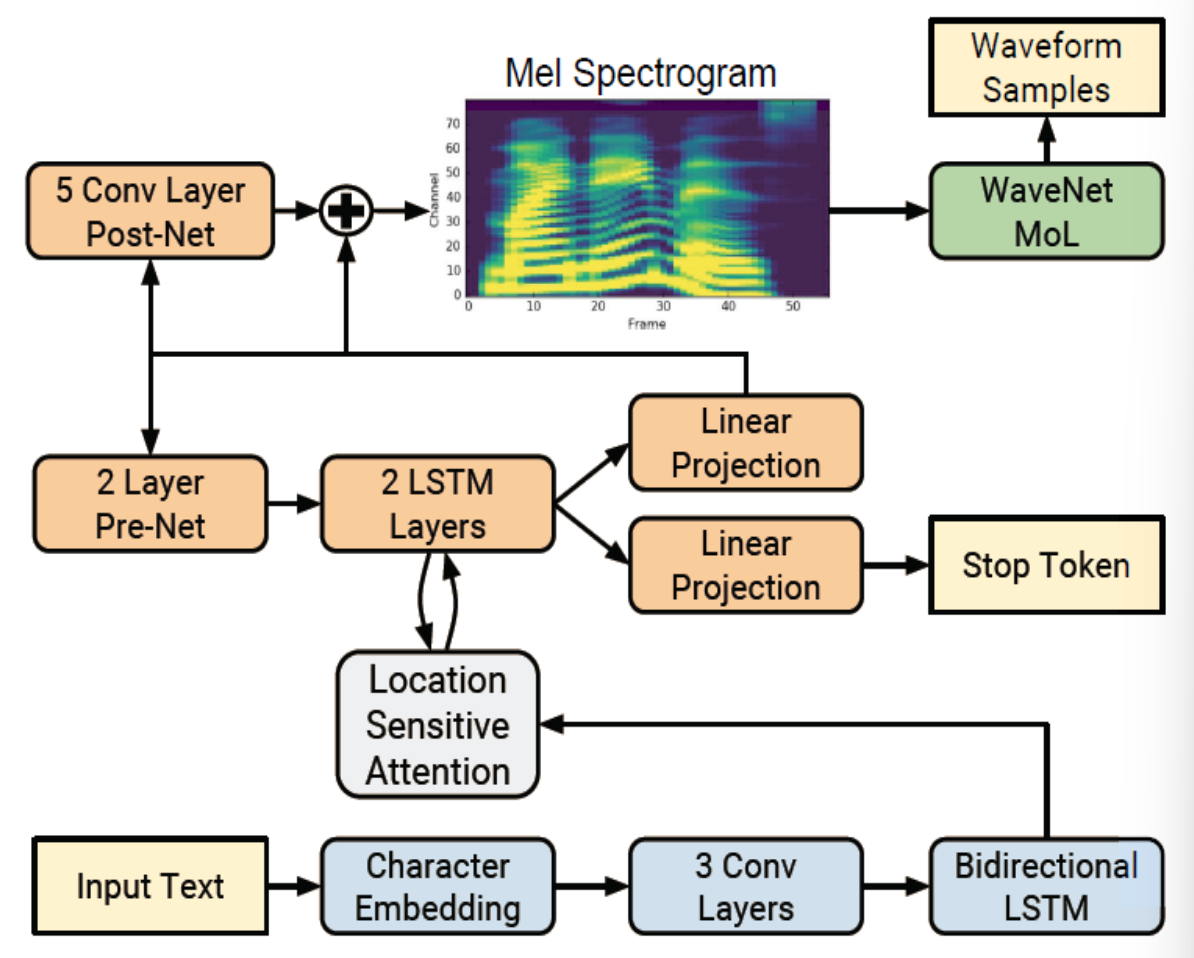
Tacotron-2 (2018). Seq2seq attention-based encoder-decoder. Only supports monolingual single-speaker. Does not model prosody explicitly.
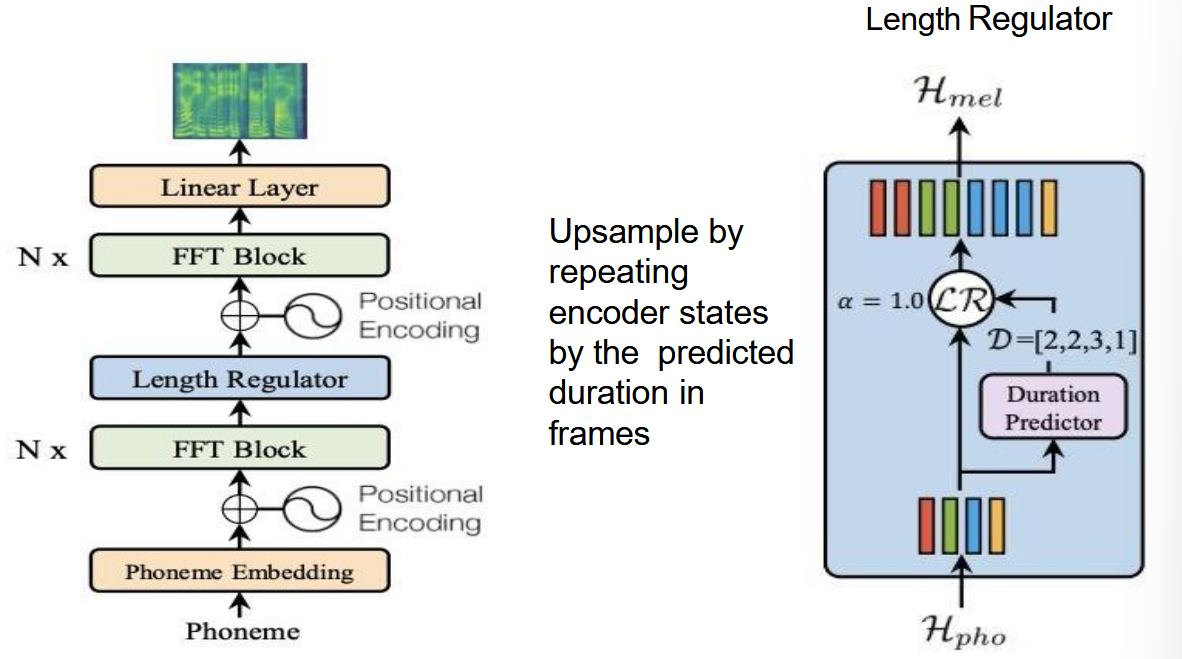
FastSpeech (2020). Non-autoregressive Seq2seq with length regulator and fully parallel transformer blocks.
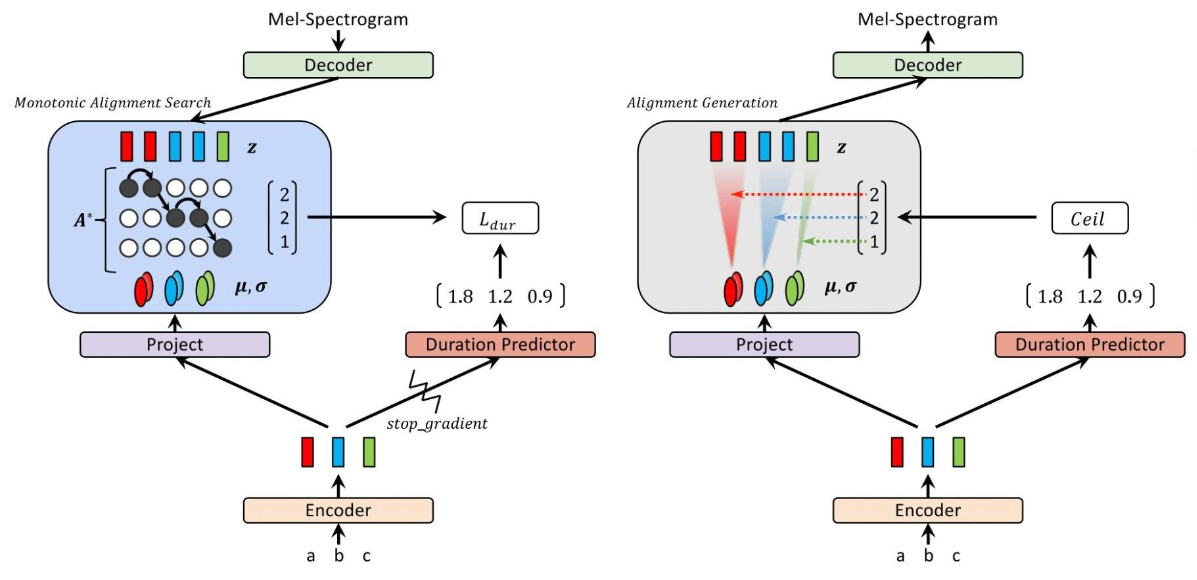
Glow-TTS (2020). Flow-based & parallel generation.
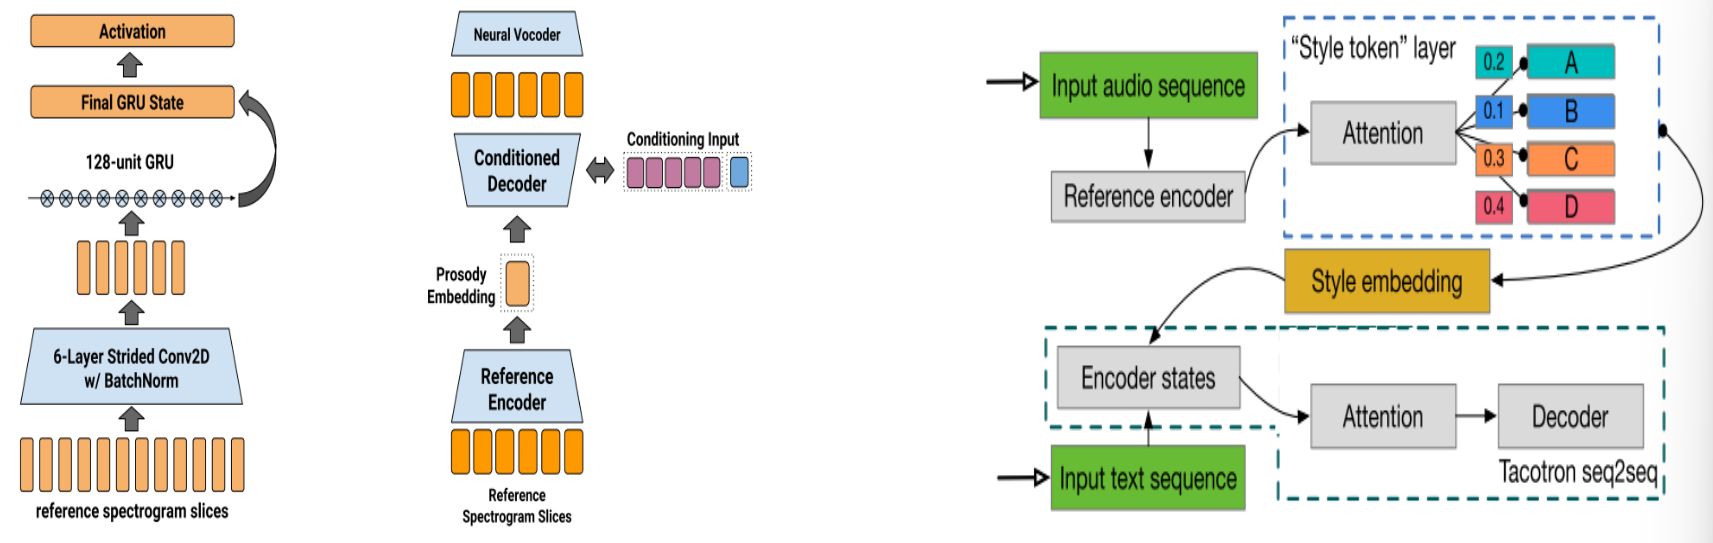
E2E-Prosody (2018) and Tacotron-GST (2018). To produce realistic speech, TTS system must implicitly or explicitly model the prosody. Add style tokens for prosody control.
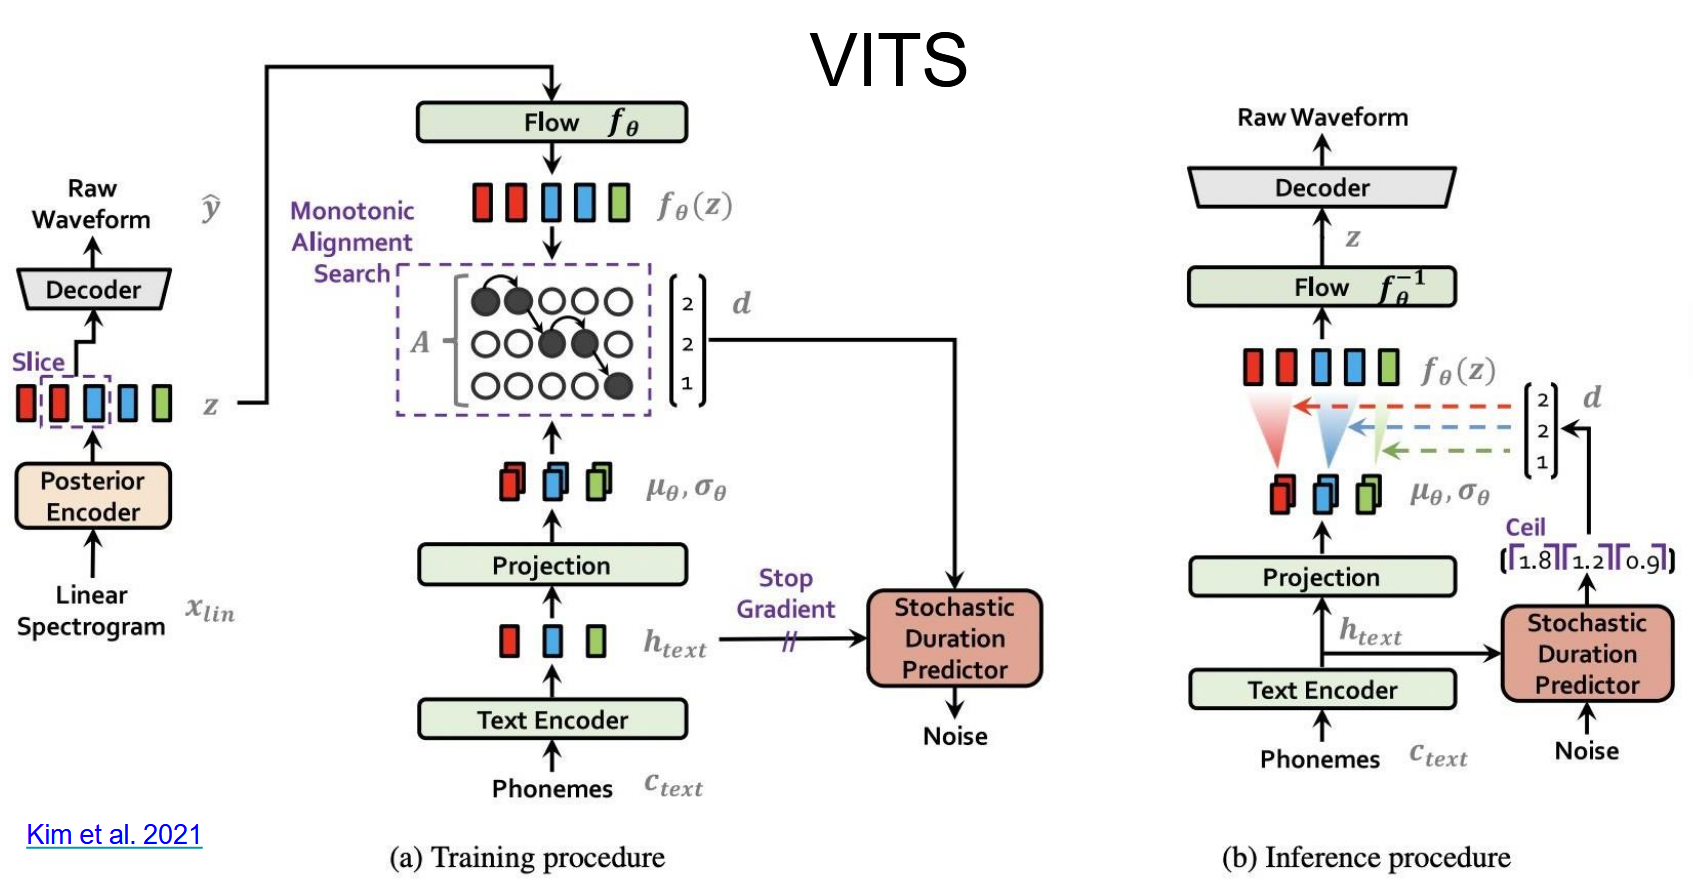
VITS: Variational Inference with Adversarial Learning for end-to-end Text-to-Speech. VITS architecture (3 Transformer blocks) trained with adversarial loss.
Spoken Language Dialog System (SLDS)
Spoken Language Dialog System (SLDS) is a system that converse by voice and take actions. Task oriented conversations.
Paradigm:
- Partially Observable Markov Decision Process (POMDP)
- Reinforcement Learning to decide actions
- Simple slot filling (ML or Regex)
- Prebuilt frames
- Calendar
- Who
- When
- Where
- Prebuilt frames
- Search Engine Techniques
- Intent recognition
- Semantic Parsing
- LLM Chatbots and dialog systems
Speech Theory
Phonetic is a branch of linguistics that studies how humans produce and perceive sounds. Modern phonetics has three branches:
- articulatory phonetics; addresses the way sounds are made with the articulators.
- acoustic phonetics; addresses the acoustic results of different articulations.
- auditory phonetics; addresses the way listeners perceive and understand linguistic signals.
Phoneme is a mental representation of a sound, not necessarily a letter.When we swap a phoneme we change the word.
Phone is the minimal linguistic unit of phonetics. Is the phonetic representation of a phoneme (the actual sound)
Allophone. Different ways to produce the same phoneme while keeping the same meaning.
Phonetic Dictionary is a list of symbols to represent sounds in a language. There are some standard phonetic dictionary:
- IPA; International Phonetic Alphabet
- SAMPA; ASCII representation of IPA symbols in various language
- ARPABET; ASCII representation of IPA symbols in English
Pronunciation Dictionary. Words in their written orthography forms do not accurately represent the pronunciation. They need to be transcribed. Phonetic transcription provide more details on how the actual sounds are pronounced -> deal with phones. Phonemic transcription represent how people interpret such sounds -> deal with phonemes (G2P).
Speech Signal is a complex mixture of periodic, aperiodic and stochastic signals -> non-stationary in nature. In practise we assume that speech is stationary over a short interval.
Speech Signal Early Processing To process speech signals in a computer -> convert the analog continuous time form to a digital signal (.wav, AIFF, AU, .raw).
- Channel number: monophonic (1 channel) or stereophonic (2 channels) -> we use mono
- Sampling rate: the number of samples of audio recorded every second measured in Hertz (Hz) -> we use 16kHz
- Sampling depth/sample precision: the number of bit per sample -> we use 16 bit (216 = 65,536 distinct amplitudes)
- Bit rate: the product of sampling rate and sampling depth
Speech Analysis is a process to find the acoustic feature representation of the original human speech waveform needed in speech processing, including TTS.
Acoustic Features include
- Vocal folds excitation parameters:
- VUV, F0 and its harmonics
- Vocal tract modulation: spectrum, formants
Acoustic Representation
- LSPs (Line Spectral Pairs)
- MFCCs (Mel-Frequency Cepstral Coefficients)
- MGCs (Mel-Generalized Cepstral Coefficients)
Formant Prediction. The formants (F2,F2,F3,F4, …) are usually defined as a broad peak or local maximum in the spectrum.
Pitch Prediction. The pitch of sound (F0) is one of the main characteristics of prosody. Pitch is directly related to intonation. F0 is used in a variety of tasks:
- Emotional recognition
- Gender recognition
- Male 70 Hz – 200 Hz
- Female 100 Hz – 400 Hz
- Speaker identification
- Breaking speech into phrases
Low Resource Languages Task (LRL).
- Monolingual Single-Speaker TTS for LRL (MoSS TTS)
- Multilingual Multi-Speaker TTS for LRL (MLMS TTS)
- Zero-Shot Multilingual Multi-Speaker TTS for LRL (Zero-shot MLMS TTS)
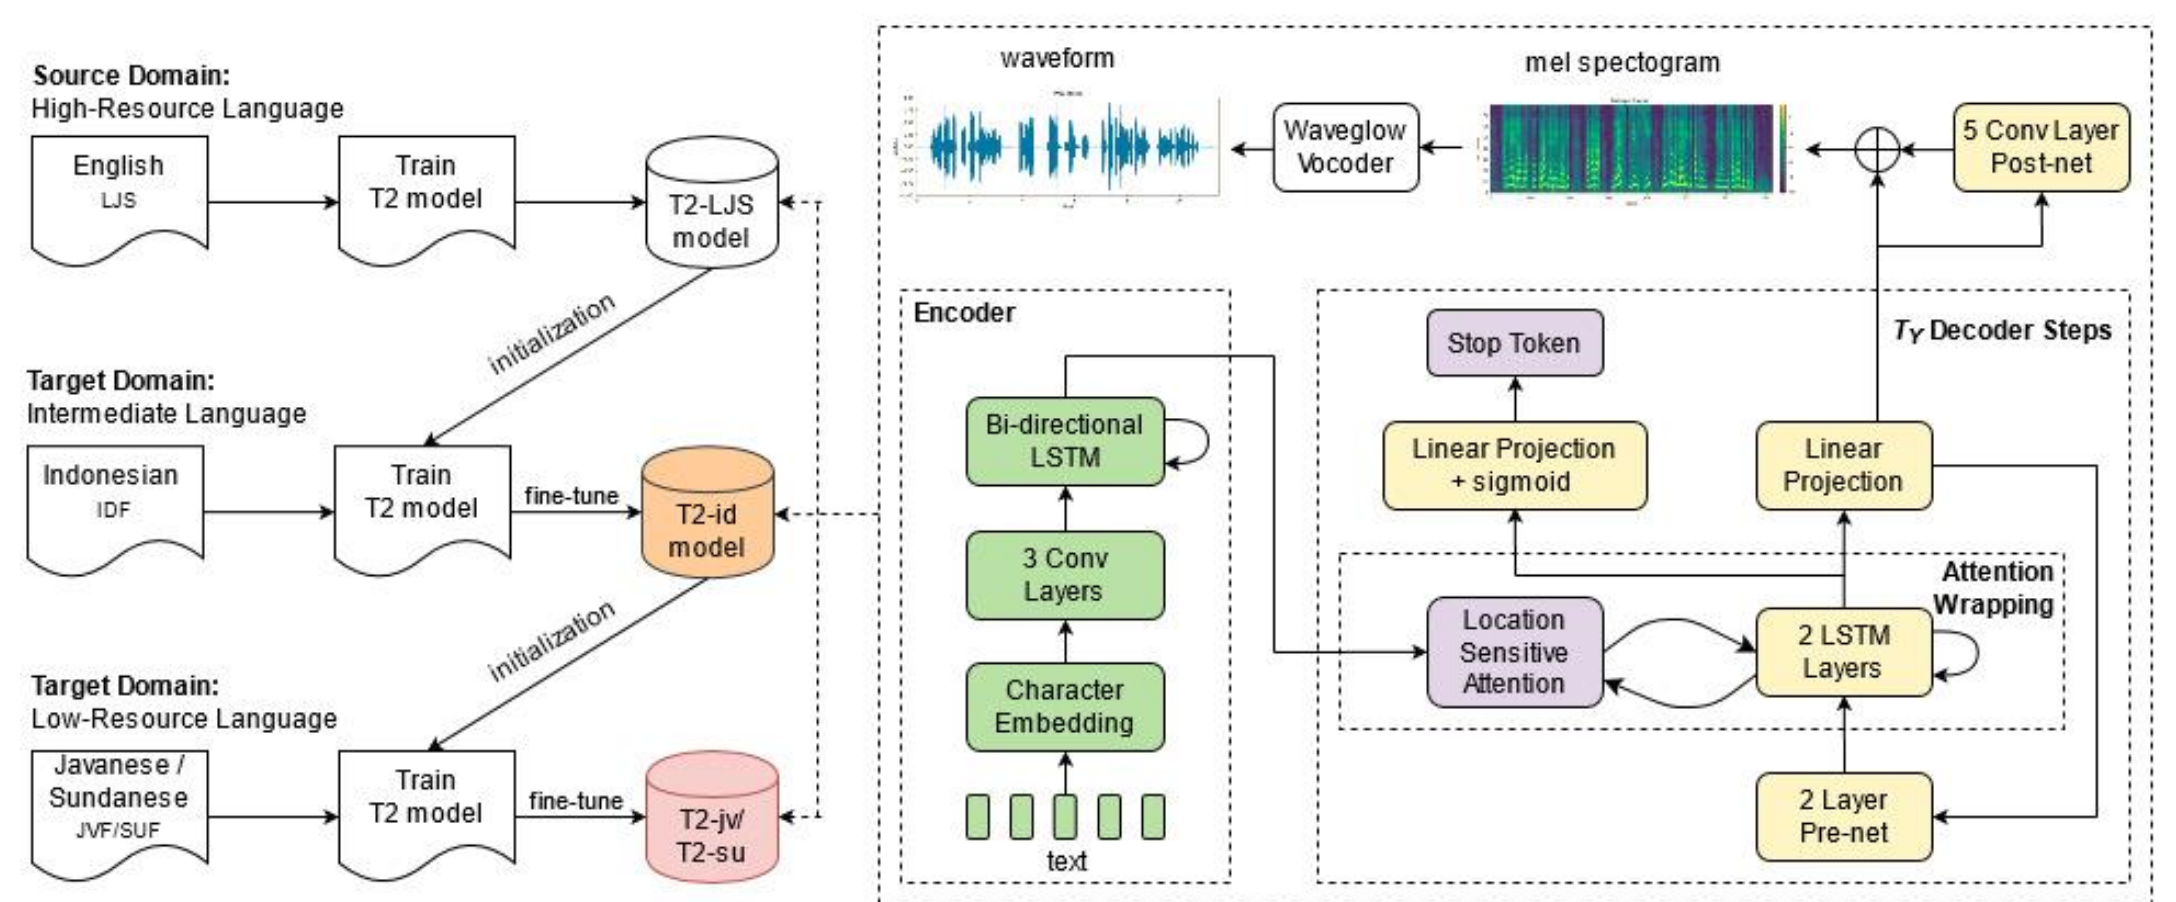
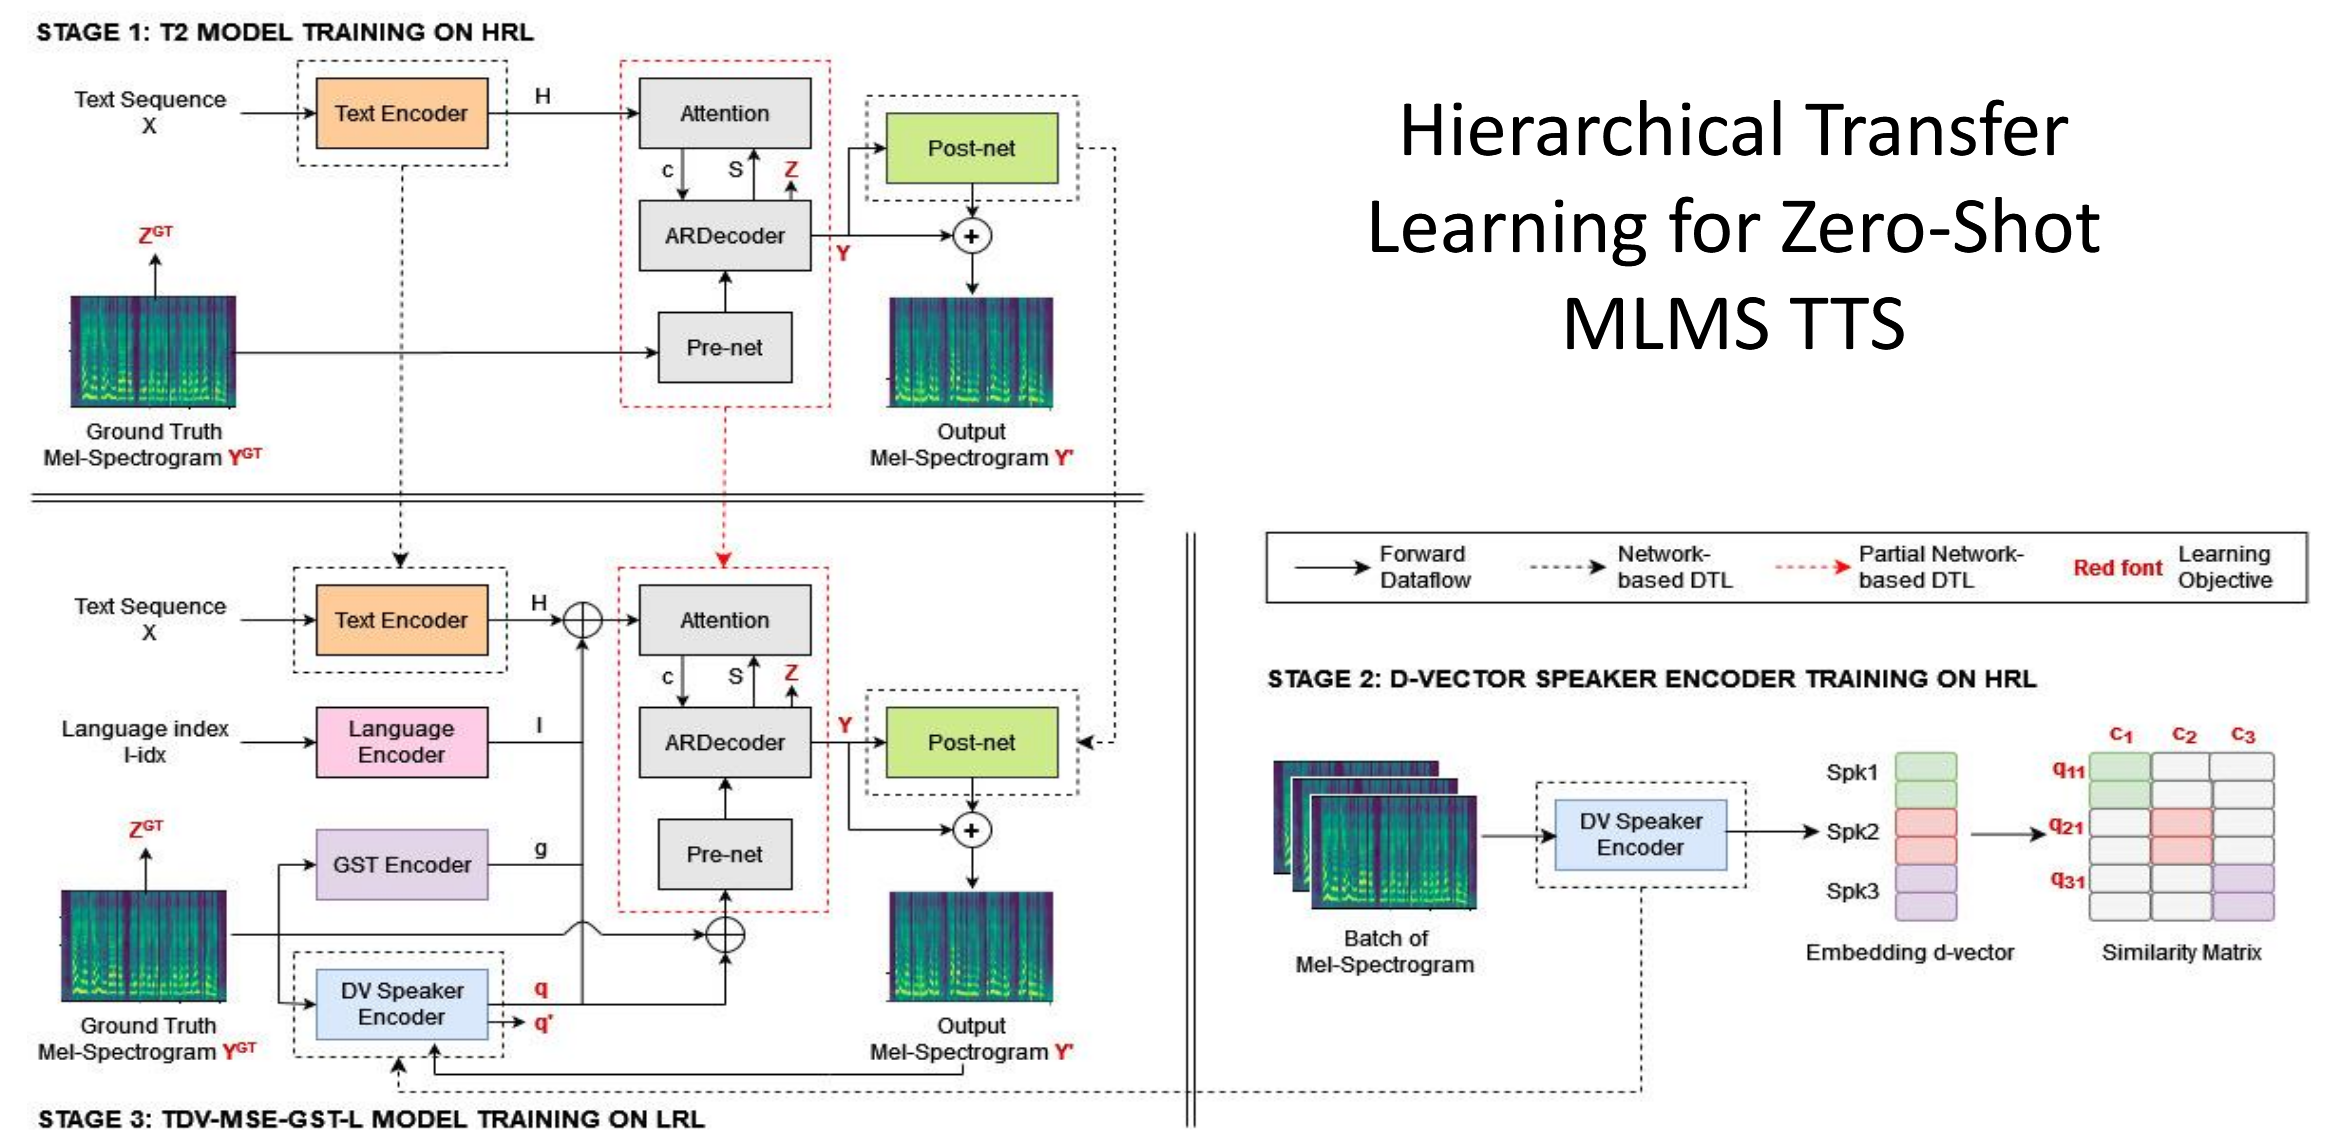
Monolingual Single-Speaker TTS: Hierarchical Transfer Learning Architecture. Transitive transfer knowledge.
Multilingual Multispeaker TTS: Hierarchical Transfer Learning Architecture.
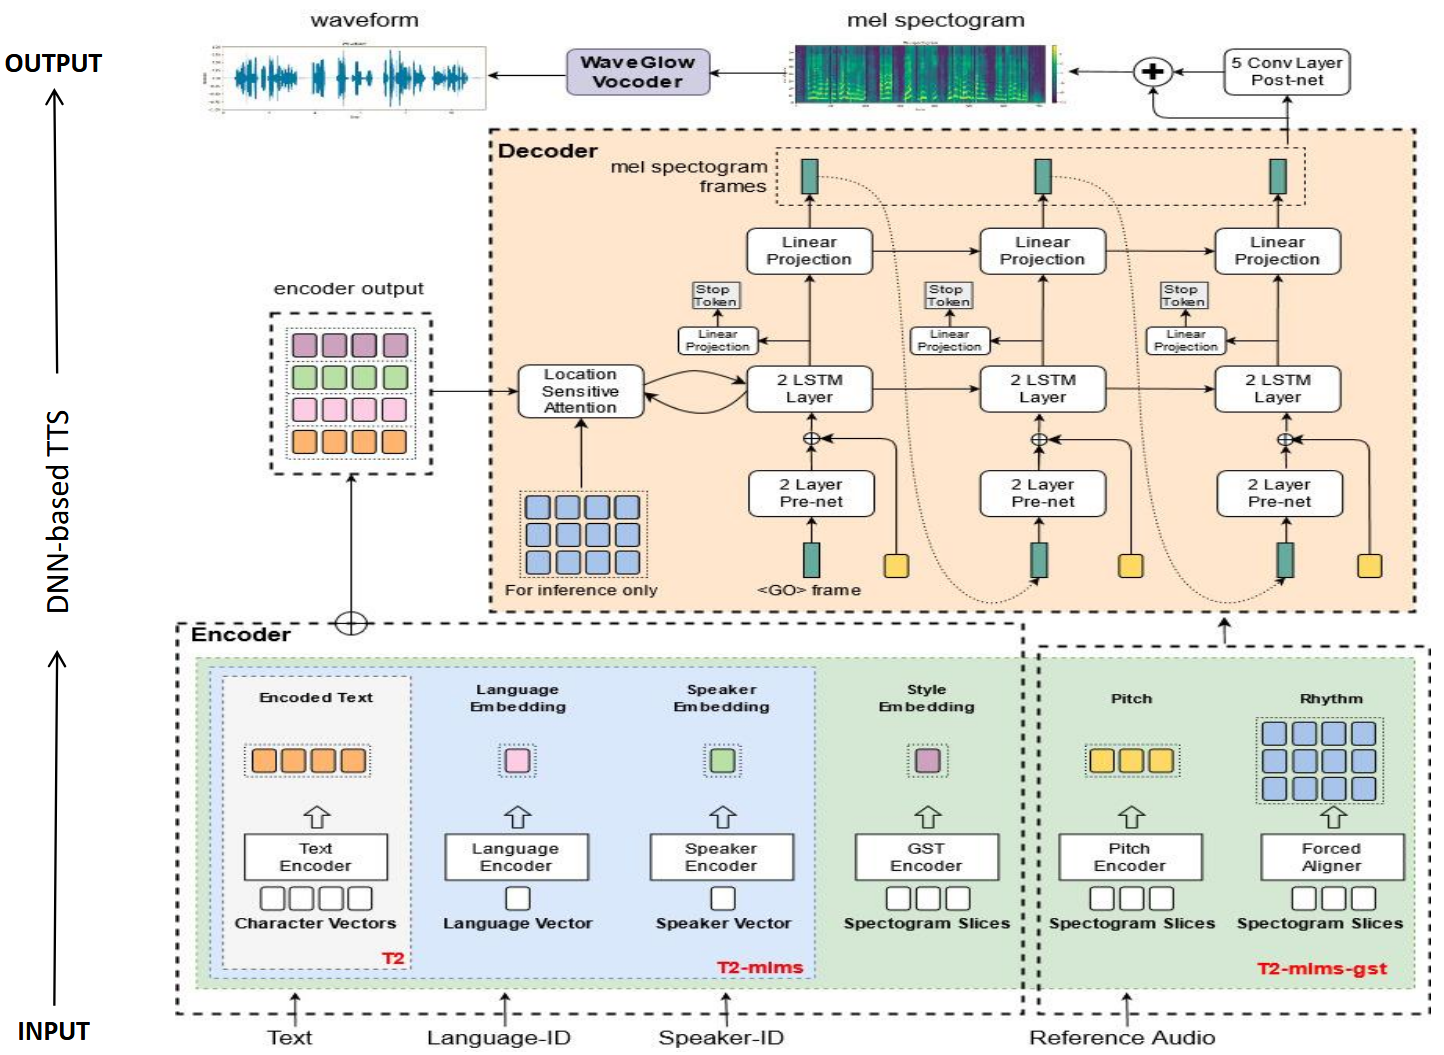
Zero-Shot MLMS TTS: Hierarchical Transfer Learning for Zero-Shot MLMS TTS.
Deep Learning for Speech Processing
Symbolic AI and Machine Learning.
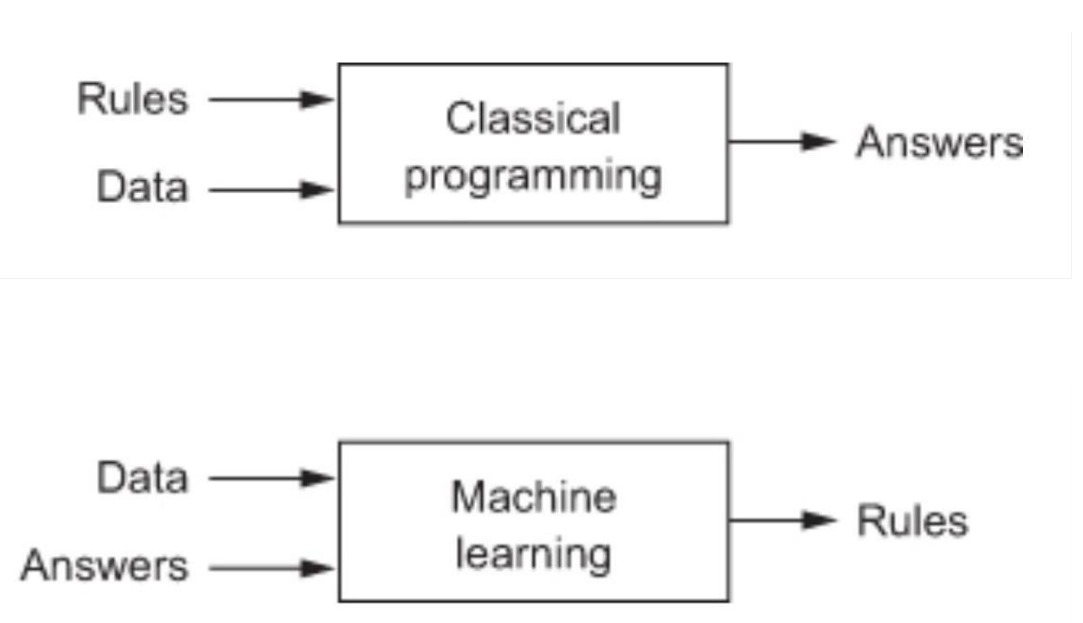
Learning Problem. Improve over task T with reespect to performance measure P as experience E increases. Task T, specific task that the computer/program has to be able to do
- Discriminative (classification)
- Generative (regression, translation, denoising, transcription) Performance measure P, how good the computer/program is at doing the task
- Accuracy, F1 score, BLEU score, etc. Experience E, data that the computer/program uses to learn the task
- Supervised learning: labeled data
- Unsupervised learning: unlabeled data
- Reinforcement learning: feedback from environment
Deep Learning Approach Based on Training Type.
- Deep Supervised Learning
- Uses labelled data (training data + target output)
- Common architectures: DNN, CNN, RNN including LSTM and GRU.
- Deep Unsupervised Learning
- Uses unlabelled data (training data without target output)
- Common architecture: AE, RBM, GAN.
- Some applications uses LSTM and RL.
- Deep Semi-supervised Learning
- Uses partially labelled data.
- Architectures: DRL, GAN, and RNN including LSTM and GRU.
- Deep Reinforce Learning
- Learning by observation that is used in unknown environments.
- Architectures: RL and DRL.
Basic Deep Neural Network (DNN) Architecture.
- Fully connected neural network (FCNN): Dense layers, feed-forward only.
- No parameter sharing
- Suited to fixed-size inputs/outputs
- Convolutional neural network (CNN): Local patterns + parameter sharing; excels on grids and sequences.
- Local receptive field
- Parameter sharing
- Spatial subsampling
- Recurrent neural network (RNN): Adds recurrence to handle sequences of arbitrary length.
- Overcomes FCNN/CNN fixed-step limitation by processing vector sequences over time
- Suited to variable-length inputs/outputs
- Long short term memory network (LSTM): RNN variant that preserves long-range dependencies.
- Addresses vanishing gradients via gated memory cells
- Gates: input, forget, output control information flow/state updates
- Bidirectional LSTM (Bi-LSTM): Two LSTMs in opposite directions for richer context.
- Processes sequences past→future and future→past; each step has access to both contexts
- Gated recurrent unit (GRU): A streamlined gated RNN.
- Merges “write” and “forget” into a single update gate; performs selective overwrites (forget = 1 − update).
- Fewer gates/params than LSTM, competitive performance
Input size vs Output size Task Variability.
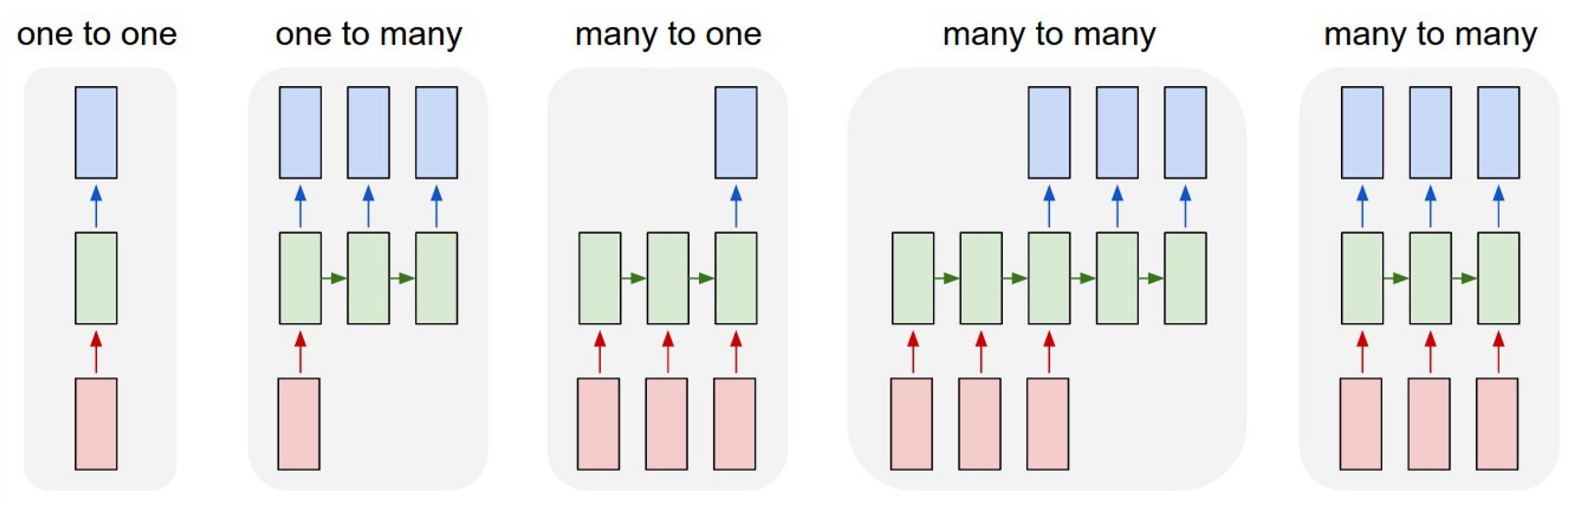
Seq2Seq Learning. Training a model to convert a sequence from one domain as input to a sequence in another domain as output.
- Famous architectures: CTC, attention-based encoder-decoder, joint CTC/A, RNN-tranducer, and Transformer.
Encoder-Decoder vs Attention-based Encoder-Decoder. Bottleneck encoder decoder:
- The complete sequence of information must be captured by a single vector.
- It poses problems in holding on to information at the beginning of the sequence and encoding long-range dependencies
The core idea of attention is to focus on the most relevant parts of the input sequence for each output
RNN and Transformers
Speech Sound
Sound is a distortion in air pressure traveling in waves that gets intrepreted by brain as sound.
Compression and Refraction. Increasing the air pressure is called compression while decreasing the air pressure is called rarefaction. Sound wave is a wave of compression and rarefaction.
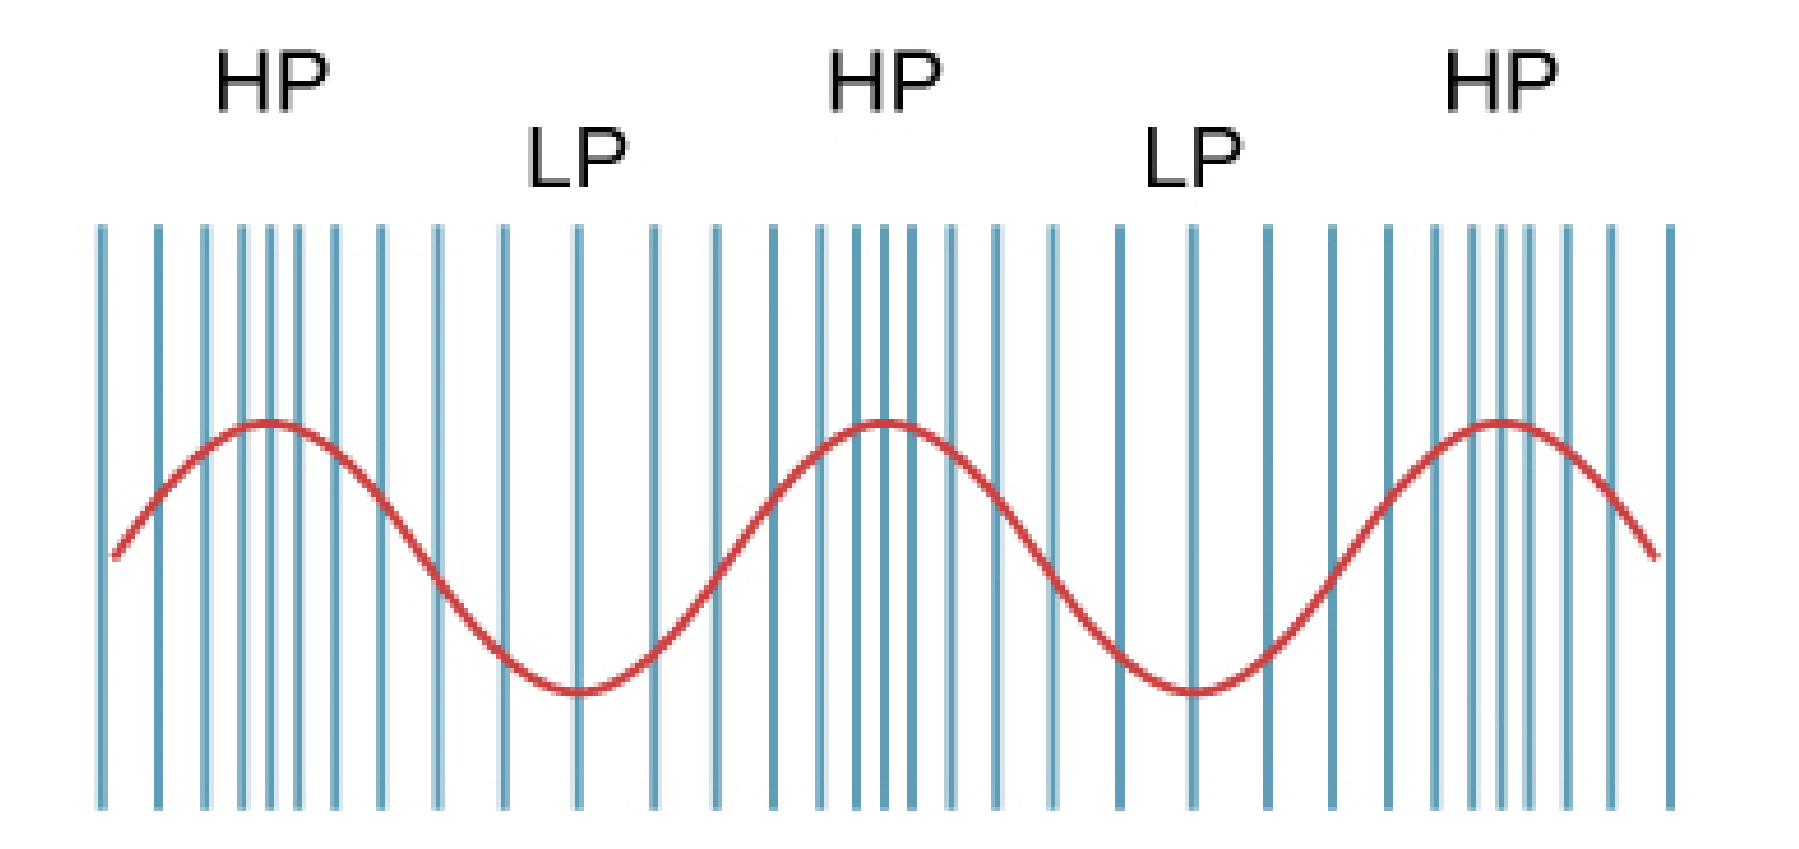
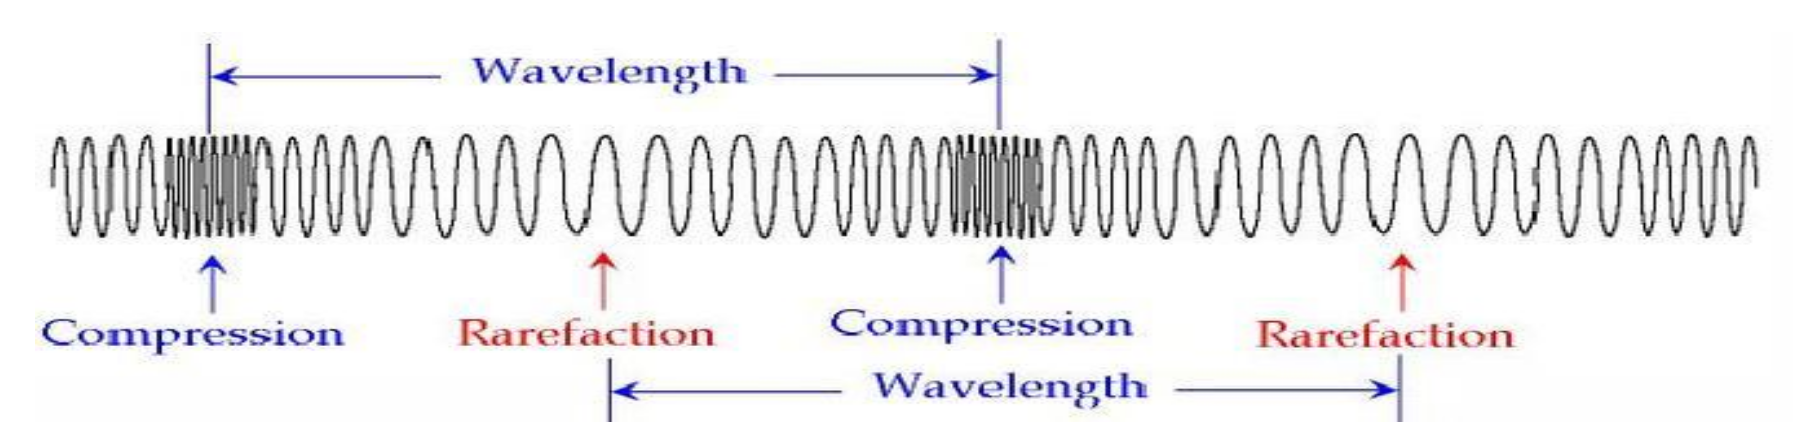
- HP: Compression
- LP: Rarefaction
Describing sound waves. Sound is a disturbance of air molecules that travels in a wave (compression, rarefaction) with the following properties
- Amplitude (perceived as loudness)
- The size of the distortion
- How much energy the wave has
- Frequency (perceived as pitch)
- The number of cycles of the wave per second.
Fundamental frequency. The “base” frequency (F0). The frequency at which that object vibrates. Males ~130Hz, females ~220Hz.
Harmonics. Integer multiples of fundamental frequency. Activated when object vibrates at fundamental frequency.
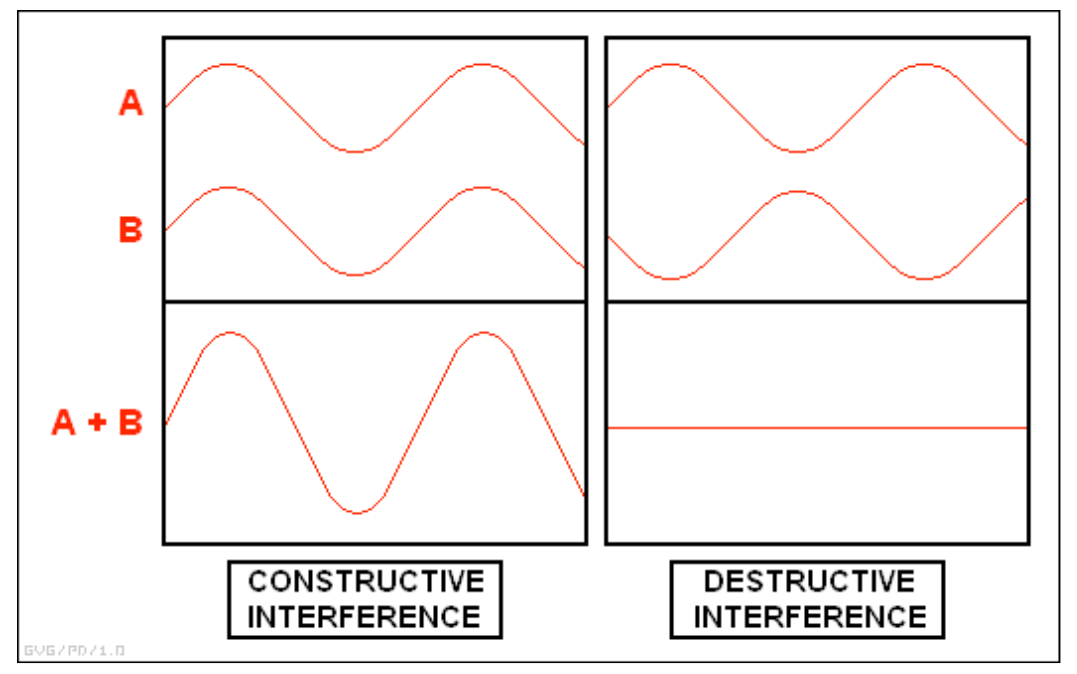
Resonance is a property of all objects. This reflection causes some interestin things to happen to the sound waves through a process called interference. We are actually interested in the resonance that occurs inside of hollow bodies like the body of a guitar: sound waves reflect off of the walls. There are two types of interference that can be created through resonance within hollow bodies:
- Constructive interference is when the peaks of the reflected waves line up. This doubles the amplitude of those waves.
- Destructive interference is when the peaks of one wave line up with the trough of a second wave. This cancels out the wave!
Speech sounds and formants.
- Vocal folds/cords: two muscular bands that produce your sound
- Vocal tract: the body of your instrument. Vocal tract has resonance bands, called formants (Formant 1 (F1), Formant 2 (F2), …).
- the trachea,
- the oral cavity
- the rounder shape of the lip
- Each speech sound can be uniquely defined by formants
Producing speech sounds.
- Your vocal folds create a fundamental frequency (perhaps 200Hz) that also has some harmonics (say, 400, 600, 800, etc).
- These harmonics resonate in the “body of your instrument”. In the case of speech, we have three “bodies”: the trachea, and the oral cavity, and the lips
- We call the most prominent harmonic band for each body (that is, the most prominent band NOT created by the F0) a FORMANT.
Formants and sound in our language. There is no 1-to-1 correlation between the physical properties (formants) and perception of speech sounds. Each speech sound can be uniquely defined by articulatory distinctive features. The production of speech sounds can be reduced to a small set of motor commands.
Phonetics.
- Allowing deep learning models to learn letter-sound mappings from data can perform much better than hand engineering phonetic structure into a recognition or synthesis system.
- Basic understanding of phonetics and speech production helps with describing and debugging spoken language systems
Pronunciation Transcription. A word can be transcribed into 2 types of transcription.
-
Broad transcription/phonemic transcription -> Grapheme-to-Phoneme (G2P)
- Converts word into a sequence of phonemes
- Uses slashes
- puff = /pʌf/
-
Narrow transcription/phonetic transcription -> Letter-to-Sound (L2S)
- Gives us extra information about how a word sounds
- Uses brackets
- [p^hʌf]
Phoneme, Phone, and Allophone. Phoneme - A phoneme is the mental representation of a sound, its what on your mind. Phone - A phone is the actual sound produced by the vocal tract. Allophone - Different ways to produce the same phoneme while keeping the same meaning. Example such as [p^h] and [p] are the same phoneme but different phones.
Prosody.
- To convey sentence-level pragmatic meanings.
- The use of suprasegmental (above & beyond the segment/phone) phonetic features.
Pitch.
- Pitch is the mental sensation or perceptual correlate of F0
- Relationship between pitch and F0 is not linear
- Human pitch perception is most accurate between 100Hz and 1000Hz. (Linear in this range, Logarithmic above 1000Hz)
Three Aspects of Prosody.
- Prominence: some syllables/words are more prominent than others
- Structure/boundaries: sentences have prosodic structure
- Some words group naturally together
- Others have a noticeable break or disjuncture between them
- Tune: the intonational melody of an utterance
Signal Processing
non-stationary by nature that consists of a complex mixture of various types of signals
- Periodic: repeats exactly with period T
- Aperiodic: any non-periodic signal
- Stochastic: noisy, unpredictable signals
White Noise is a particular type of a stochastic signal. It is completely random, however its characteristic does not change over time.
- The signal values at any two different times are completely uncorrelated.
- White noise is specified by a mean value and variance .
Sinusoids is a deterministic periodic signal. The projection of a fixed length vector rotating at a constant angular velocity.
- Amplitude is the length of rotating vector.
- Frequency is the number of cycles per second (1/T, T is period). One full rotation (), if where w is angular frequency.
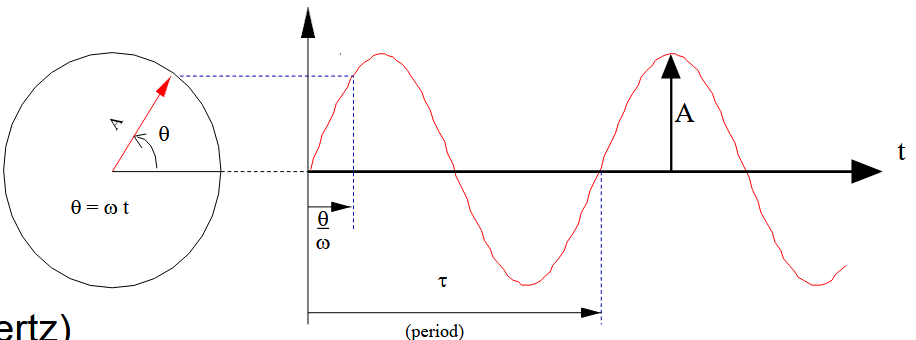
Phase. Two sinusoids with equal frequency still may be different. In order to fully describe a sinusoid, one needs to specify
- Amplitude
- Frequency
- Phase
Wave in Time Domain wave is expressed as a function of time in cosine or sine form.
Note that wave usually be represented as in fourier analysis where we do not need to specify the phase. Using the phase, we can pick one either cosine or sine wave.
Stationarity. A signal is stationary if its statistical properties do not change over time.
- A sine wave of constant amplitude & frequency
- Noise of constant mean and variance
Speech & Quasi-stationarity. in practice we normally assume that speech is stationary over a stationary over a short interval.
- a complex mixture of periodic, aperiodic and stochastic signals
- non-stationary by nature
- Interval of stationarity is normally about 10 ms.
Fourier theorem. Any periodic signal of frequency can be constructed exactly by adding together sinusoids of with frequencies (f0, 2f0, 3f0, …) each with appropriate amplitude and phase
Fourier analysis is a mathematical process used to solve complex waveform problems by decomposing the wave into its sinusoidal components.
- finding unkown and for a known waveform function
Spectrum. Any periodic function can be characterised by the amplitude and phase of its sinusoidal components. This characterisation is called the spectrum.
The Fourier Transform. Allows us to move between the time domain and the frequency domain.
Digital Signals
Digital Signal is. A sequence s[n], where s are not only finite, but can only take a finite set of values and may take complex values.
Example of Digital Signal.
- DC Signal
- Unit Step Signal
- Unit Pulse
- Pulse train
- Impulse Function
- Sinusoids
- Exponential
- Complex Exponential
Sampling
Sampling is measuring the instantaneous value of a signal at regular discrete intervals.
Quality metrics of sample.
- Sampling rate (): the number of samples per second.
- Sample depth : The audio sample can represent a higher range of amplitudes measures in bits. 8bit -> 2^8 = 256 amplitude values.
- Bit rate: the product of sampling rate and sample depth. Measured in bits per second (bps).
Nyquist rate. The minimum sampling rate necessary to preserve the maximum frequency.
- The sampling frequency must be at least twice the highest frequency present in the signal
Nyquist frequency. The highest frequency that can be represented by the sampling rate. Given a sampling rate, the highest frequency that sampling rate measure is called Nyquist frequency.
- Measured at half of sampling rate
Aliasing. Occur when sampling rate is too low (below Nyquist rate)
- Cause a lower frequency component to appear in the sampled data